Picture this: you ask the agent to play a match in a ready-made browser game. It makes a few moves, describes the position, and goes quiet. The match is still going. You type "keep going." It moves the pieces again and waits for the next message. At some point it turns out that the most repetitive part of this is on you.
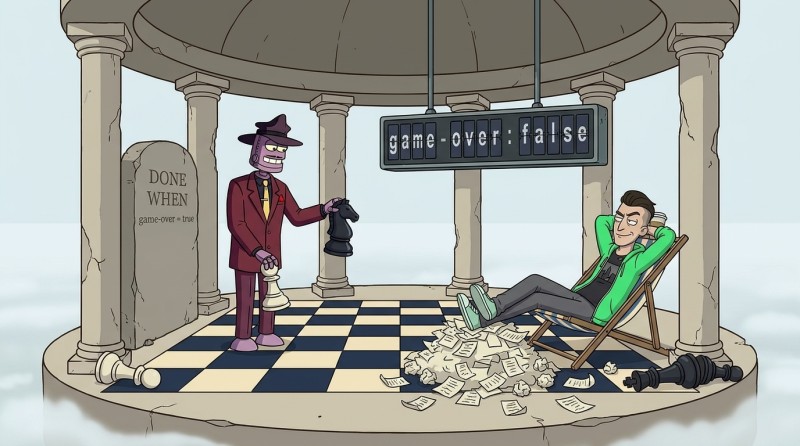
A goal is an objective with a completion condition that you set for the agent with the /goal command. For example: "play both sides until the page shows the match is over." After each turn of work, a separate model checks the conversation to see whether the goal has been met. If not, the work continues without you having to say "keep going." You get to wait for the result, though an obstacle or an error can still stop the work earlier.
We'll start with a ready-made condition for the game, then write goals for search, a form, and a mobile page. Each one will have a clear outcome and a way to check it. Along the way we'll also cover how to ask the agent to write the condition for you, and how to tell a real completion from a stop with no result.
What keeps /goal going
Two different mechanisms are involved in the conversation around the game example, and it's easy to mix them up. One performs actions in the browser: it clicks, enters moves, reads what the page shows. The other doesn't click anything - it reads the whole conversation and decides whether to keep the work going.
The first is Playwright, a browser tool connected ahead of time through MCP. The second is started by the /goal command. Playwright moves the pieces, /goal decides when it's time to stop - two different jobs, even when from the outside it looks like the same thing is happening.
| Who acts | What happens |
|---|---|
| The agent, through Playwright | performs the next action in the browser and gets an observation - what the page actually showed |
The /goal evaluator | once the agent finishes its turn, reads the conversation and decides: the condition isn't met yet, it's already met, or it can't be met at all |
An important detail: the check doesn't happen after every mouse click; it happens after the agent finishes its turn - roughly speaking, its entire response. Within one such turn the agent can easily take several actions in a row: move a piece, read the result, react to it. /goal only steps in afterward, once there's something to evaluate.
/goal doesn't add Playwright or any other tools - it only watches work that's already underway. And it doesn't waive the usual permission prompts: if the settings require confirmation for some action, the agent will still ask for it, goal or no goal.
Get the game ready to run
Before you set a condition, the example needs to be in working order: the page opens at a known address, the tools for playing on it are already connected (Playwright, in our case), and the page carries a marker that shows whether the match is over.
In our example that's a data attribute: data-game-over="false" for a match still in progress, and data-game-over="true" for a finished one. Whoever wrote the game page sets this contract - the agent doesn't invent it, it just reads it.
Checking this is easy: ask the agent to open the page and read the attribute's value. For a match that just started, it'll get false. and that's fine - exactly what's expected at the start.
If the attribute isn't on the page at all, it's too early to set a goal. A condition can only rely on something you can actually read, so the first step is to bring back the marker itself, not improvise a substitute on the spot. And once the example is set up, don't change the criterion partway through the match or bolt a separate timer onto the game just to make the demo finish faster. The condition stays the same from start to finish.

Run the finished goal
Next comes the actual command. The condition for our example might read like this:
/goal play both sides in turn through the page interface.
After each move, read data-game-over and show what's visible
on the page. The match counts as finished when data-game-over
becomes true. If that hasn't happened after 40 moves,
stop and describe where you got stuck. Don't change the game code.
Let's break the phrasing down into parts. You'll need these same parts for your own tasks:
- "play... through the page interface" - a measurable action the agent can actually show in the conversation;
- "the match counts as finished when data-game-over becomes true" - the only thing here that counts as an actual outcome. This is exactly what the evaluator will look for in the conversation;
- "after each move, read... and show" - the very fact that gives the evaluator something to check at all. Without this line it has nothing to look at;
- "if that hasn't happened after 40 moves, stop and describe" - a separate instruction for when true never comes. It isn't part of success; it's a way to stop the work without it: it caps the goal's scope, but doesn't stand in for the outcome. And it's still an instruction in the text, not a hard-coded timer - the evaluator checks it against the conversation too;
- "don't change the game code" - something that shouldn't happen along the way while the agent works toward the outcome.
What the outcome will actually be isn't known ahead of time - you can't promise a specific winner, how long the match runs, or even that it finishes. But it is clear what the agent has to show: the game state it read and the reason it's continuing or stopping.
What to build your own condition from
Start with the phrase "the task is done when...". If what follows sounds like "everything got better," the agent will have to guess what you meant. Replace the judgment call with behavior you can actually see: "after clearing the search, all the cards are visible again." Several checks are fine as long as they describe one outcome, like a fixed search.
- Name the outcome. "Fix the search" sets a direction, while "the search finds a card by name and returns the full list after clearing" sets a finish line.
- Spell out the check. Write down what to open, what to enter, and what response is expected. Ask for the actual result to be shown in the conversation so the evaluator can read it.
- Limit the changes. If only styles need to change, say so. If the agent is testing a finished game, forbid changing its code just to get the outcome you want.
- Plan for a stop without success. For example, after three fix-and-recheck attempts, the agent should describe the problem that's left. This is a limit on the work, not another way to declare the task done.
Before you launch it, check that the agent has access to the right page, files, and tools. The address and element names in the condition need to belong to your own project. A text-based cap on attempts helps manage the work, but it isn't a hard technical limit on time or cost.
Notice the arrow that loops back. If the outcome hasn't been reached yet, the agent gets another turn and can fix the problem, then check again. But leaving that loop doesn't always mean success: an obstacle or an agreed-upon limit needs to be called out separately. The diagram shows the condition's working logic; the agent and the evaluator track the attempt limit through the conversation.
Three examples for your own tasks
Below are sample conditions for pages that already exist. Swap the addresses, data, and expected behavior for your own before you run them. These are example conditions, not reports of finished work.
Fix search in a catalog
Say a local catalog has "Atlas" and "Orion" cards, but the list stays empty after you clear the search. A request like "make the search work properly" says nothing about the behavior you actually want. Here three specific cases are more useful:
/goal fix the search in the catalog at http://localhost:3000/catalog.
Done when the query "atlas" finds the "Atlas" card,
the query "zzzz-no-match" shows "No results found",
and clearing the field returns all the original cards.
Check all three cases through Playwright and show in the conversation
the query, the expected result, and the cards or message
actually visible. Repeat all three checks after the last fix.
Change only the search logic; don't change the catalog data or styling.
If the problem remains after three fix-and-check attempts,
stop and list which cases still don't work.
The word "all" matters here: finding one card doesn't yet confirm the search is fixed. The catalog data is fixed, so you can't get the desired outcome by renaming cards. And it's worth rechecking after the last fix, too - fixing how the field gets cleared could have broken the search itself.
Check a form without making fixes
A goal's outcome can be a list of observations. Say you need to check a finished sign-up form, and you want to discuss any fixes separately. Then the goal ends once all the cases have been checked, even if it finds bugs.
/goal check the form at http://localhost:3000/signup
through Playwright, without changing the project files.
Check two cases, each starting from an empty form:
1. Click "Sign up" without filling in any fields.
Expect a required-field hint, no registration happens.
2. Enter "alex" in the email field and fill in the other required
fields with valid sample values, then click the button.
Expect an email format error, no registration happens.
Done when the conversation has a report on both cases:
what was entered, what was expected, what the page showed, whether it matched.
Don't submit the form with a valid email, and don't create accounts.
If a page or element can't be opened, stop the check
and state which case was left untested and why.
Here's the difference: "check the form" and "make the form work" are two different tasks. Here a bug in the form doesn't stop the report from being finished, as long as the agent actually checked both cases and showed the results. But an unreachable page does stop it: guesses instead of observations don't close out the goal.
Fit the page on a phone
"Make it look nice on mobile" leaves too much up to the agent's taste. Pick a specific page, window sizes, and elements that need to stay accessible.
/goal fix the styles of the page at http://localhost:3000
for window sizes 390x844 and 1440x900.
Done when there's no horizontal scrolling at either size,
the heading and the "Start" button are fully visible and don't overlap,
and clicking "Start" still opens the game section.
Check both sizes through Playwright after the last fix.
Show screenshots, the result of the click, and the measured
scrollWidth and clientWidth of the page's root element:
scrollWidth shouldn't exceed clientWidth.
Change only CSS. Don't hide content or cut it off
to get rid of the scrolling. Keep the text and the game's behavior as they are.
If the conditions aren't met after three fix-and-check attempts,
stop and show the remaining mismatch.
The sizes here are the browser window's width and height in pixels. scrollWidth shows the content width including the part past the edge, while clientWidth is the available width. Comparing them helps you catch overflow, but on its own it doesn't prove the text isn't cut off or the button is reachable. That's why the condition also asks for screenshots and a click. And two sizes don't prove the page works on every device either - they just set the scope of this particular task.
Ask the agent to draft a goal
You don't have to write the condition from scratch. The Claude Code Best Practice collection lists two tips from the community: ask the agent to suggest goals based on the project's context, and have it draft the wording itself after reading the chat and the files. Below is an adaptation of these techniques for a small task.
If it's not yet clear what to hand off to a long-running task, start with a regular message, without /goal:
Read the current conversation and the project files relevant to the task.
Suggest three useful goals that can end in a verifiable
outcome. For each one, name the outcome, how to check it,
the boundaries of the changes, and what's still missing to launch it.
Base this on what we've agreed on. Don't launch the goals yet,
don't change any files. If the intent is unclear, ask questions.
Pick one goal. Long-running work isn't valuable in itself: a fixed search is more useful than several hours of vague "improvements." When the task is already clear, you can skip the first request and go straight to asking for a draft condition:
Write the /goal text for the chosen task based on our conversation,
the project files, and its documentation. Don't do anything yet.
State the observable outcome, how to check it, and what to show
in the conversation. Add the boundaries of the changes and a stop
condition in case it doesn't succeed. Don't invent addresses, commands, or
readiness signals: find them in the project or check with me.
Return one finished text and list any unclear points separately.
Before you send off the draft, check the meaning. Does the outcome match what you actually wanted? Does the stated page exist? Did the agent quietly allow itself to change data or add features along the way? If unclear points are still listed at the bottom, sort those out first. Run it only once the text is settled: the /goal command starts working right away.
Check the status and stop the work
While a goal is active, you can watch its progress: the /goal command with no arguments shows the current state - the condition, how much time and how many turns have passed, and the last reason the evaluator returned.
You can also stop a goal early - with the /goal clear command. It clears the condition even if the match isn't over yet.

There's only one confirmed result here: the condition is met, and that shows in the evaluator's answer in the conversation. Clearing the goal with /goal clear is also a clear outcome, but it's your decision to stop, not proof that the work is done. Every other way a goal can stop on its own doesn't confirm an outcome.
If the evaluator decides the condition can't be met, or a limit written into the condition kicks in - the goal will also stop on its own, without your command. Errors are trickier: the goal clears itself only on an error that has to be fixed by hand (running out of credits, for example). After a temporary failure it stays active and waits for a retry or for your message, and if the agent makes no progress for several turns in a row, Claude Code hands control back to you, again without clearing the goal. None of this is the same as "the match was played": above, the stop was either confirmed by the evaluator or you decided yourself to clear the goal, and here it's neither. Don't force the example into a happy status by weakening the condition after the fact: if the work is stuck, it's smarter to clear the goal with /goal clear and plainly describe where it got stuck than to rewrite the condition until it's guaranteed to pass.
What the checking model actually gets
The /goal evaluator doesn't see the page itself, only the conversation: what the agent wrote, and what it copied into it from the browser observations. The evaluator has no tools of its own - it doesn't reopen the page or run commands itself; it only reads the text that's already piled up.
The consequence is simple. The agent saying "the match is over" doesn't by itself prove anything to the evaluator or to you. What proves it is the result the agent actually read off the page - that same data-game-over value. The first is a claim, the second is an observation, and they're different things even when they sound alike.
It's worth understanding the limits of the signal itself, too. data-game-over reports the state of one particular app - whatever the page's author built into it. It says nothing about whether the whole match was played strictly by the rules of chess without a single mistake. In the same way, the absence of scrolling doesn't prove the button works. Pick a signal that matches the outcome you actually want, and don't read more into it than it says.
What this changes about the work
For your own task, you can follow the same short route:
- a clear outcome and a way to check it that's actually available;
- a condition with boundaries on changes and on stopping, set with the
/goalcommand; - a status you can check at any moment -
/goalwith no arguments; - a conclusion backed by observations and check results;
- a goal cleared by hand with
/goal clearif the work gets stuck or the condition turns out to be a bad fit.
Automatically continuing the work and deciding what to do next are two different things. You can hand the first one off to /goal within a single session. The second - figuring out what actually came of it, clearing an unfinished goal, setting the next task - is still on you.
The exact behavior of the evaluator and the format of the status can vary a bit depending on the version of Claude Code. The general principle - evaluation from the conversation, not direct access to the page - stays the same.
GO TO FULL VERSION