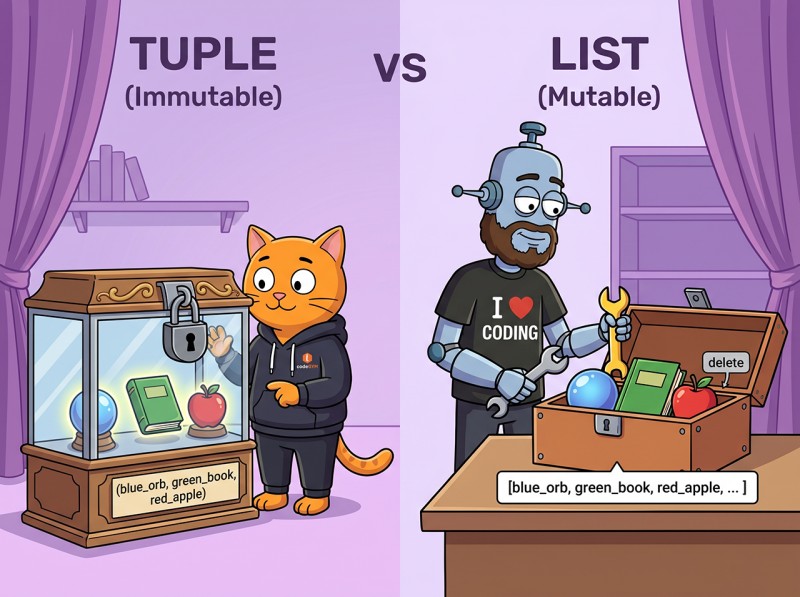
Lists are mutable; tuples are immutable. That single fact explains 80% of the differences. Lists use square brackets and methods like append, extend, and remove to change their contents. Tuples use parentheses (or just a comma) and have no mutation methods. The immutability of a tuple has two important consequences: tuples are hashable, so they work as dict keys and set elements; and CPython can optimize them in ways lists don't allow, making them slightly faster and more memory-efficient. For records with named fields (coordinates, RGB colors, database rows) the modern choices are collections.namedtuple, typing.NamedTuple, and dataclasses.dataclass(frozen=True); reach for plain tuples when positional access is enough. This piece is one of 17 short explainers in our Python Concepts Explained reference.
Key Takeaways
Mutability is the core distinction. Lists can change; tuples can't. Everything else falls out of that one rule.
Hashability follows from immutability. Tuples can be dict keys and set elements (if their contents are also hashable). Lists never can.
Tuples are slightly faster and smaller. Roughly 20-30% less memory for the same elements, and ~10% faster creation and access. The difference matters at scale.
The tuple-of-mutables trap: a tuple containing a list still lets you mutate the list, even though the tuple itself is "immutable". The container is locked; its contents aren't.
For records with named fields, reach for collections.namedtuple, typing.NamedTuple, or dataclasses.dataclass(frozen=True). The last is the modern default unless tuple-style positional access matters.
Two questions to pick a container; the memory savings make the choice obvious when you have millions of them.
Two Containers, Two Different Jobs
Lists and tuples both hold an ordered sequence of items, both support indexing and slicing (for the rules see our slicing explainer), and both can contain arbitrary Python objects. The difference is intent.
A list is a collection of similar items whose count and contents can change over time: a shopping cart, a log buffer, a sequence of measurements.
A tuple is a record with a fixed structure where each position has a specific meaning: a (latitude, longitude) coordinate, an (red, green, blue) color, a database row.
That semantic distinction predates Python and shows up in most languages with both types. The Python-specific quirks (hashability, the comma syntax, internal optimizations) all flow from immutability.
Syntax: () vs [] and the Comma Trick
Lists use square brackets; tuples use parentheses (sometimes).
l = [1, 2, 3]      # list
t = (1, 2, 3)      # tuple

l_empty = []        # empty list
t_empty = ()        # empty tuple
The catch: parentheses are also used for grouping expressions, so a single value in parentheses is just that value. To create a single-element tuple, add a trailing comma.
x = (42)            # just the integer 42
y = (42,)           # one-element tuple

print(type(x))      # <class 'int'>
print(type(y))      # <class 'tuple'>
The deeper rule: it's the comma that makes a tuple, not the parentheses. You can drop the parentheses in many contexts.
point = 3, 4        # tuple (parentheses optional)
x, y = point        # unpacking, no parentheses needed

def divmod_demo(a, b):
    return a // b, a % b   # returns a tuple
The tuple(iterable) constructor builds a tuple from any iterable, the same way list(iterable) does for lists.
Mutability: The One True Distinction
The defining difference, and the one every other characteristic flows from.
l = [1, 2, 3]
l[0] = 99
l.append(4)
print(l)            # [99, 2, 3, 4]   ← list changed

t = (1, 2, 3)
t[0] = 99           # TypeError: 'tuple' object does not support item assignment
t.append(4)         # AttributeError: 'tuple' object has no attribute 'append'
Lists have mutation methods: append, extend, insert, remove, pop, clear, sort, reverse, plus item and slice assignment (covered in our append vs extend explainer). Tuples have only the read methods that any sequence has: count and index.
Rule: if you might want to change the collection later, use a list. If you want the type system (and your future self) to enforce that it won't change, use a tuple.
Hashability: Why Tuple Can Be a Dict Key
The most useful consequence of immutability. An object can be a dict key (or a set element) if it implements __hash__ consistently with __eq__. Hashability requires that two equal objects produce the same hash, which only works reliably if the object can't change after creation.
# Tuples work as dict keys and set elements
coords = {(0, 0): "origin", (1, 1): "diagonal"}
visited = {(0, 0), (1, 0), (1, 1)}

# Lists do not
bad = {[0, 0]: "origin"}    # TypeError: unhashable type: 'list'
The same applies to set elements: set([(1, 2), (3, 4)]) works; set([[1, 2], [3, 4]]) raises. For typed records keyed on tuple identities (a chess board addressed by (row, col); a directory tree addressed by (parent_id, name)), this is the dominant reason to prefer tuples.
Subtle: a tuple is hashable only if all its contents are hashable. (1, 2, [3]) raises TypeError on hashing because the inner list is unhashable. Tuples of tuples are fine; tuples of lists are not.
Performance and Memory
The asymptotic complexity of indexing, length, and iteration is the same for both: O(1) for indexing, O(n) for iteration. The constant factors differ.
Lists pad their internal storage to support future appends without re-allocating every time; tuples never do, because they can't grow. For sequences that won't change, tuples save 20-30% of the memory. On a million 3-element collections, that's 24 MB.
import timeit

# Tuple creation is ~2x faster
timeit.timeit("(1, 2, 3, 4, 5)", number=10_000_000)   # ~0.15 s
timeit.timeit("[1, 2, 3, 4, 5]", number=10_000_000)   # ~0.35 s

# Iteration is similar (no significant difference)
timeit.timeit("for x in (1,2,3,4,5): pass", number=10_000_000)   # ~0.55 s
timeit.timeit("for x in [1,2,3,4,5]: pass", number=10_000_000)   # ~0.55 s
The difference is creation, not iteration. For hot code paths that build millions of small sequences, this is real money. For everyday code, both are too fast to matter.
CPython Internals: Why Tuples Are Faster
Three reasons account for the tuple advantage in CPython.
1. Smaller C struct
The list object holds a pointer to a separate array of items, plus the array's allocated capacity (so it knows when to grow). The tuple object stores items inline at the end of its struct, no capacity field needed. Fewer fields, less indirection, less memory.
2. No over-allocation
Lists keep extra slots so append doesn't re-allocate every time. A list of three items might hold capacity for eight. Tuples are exactly the size they hold; no waste, no bookkeeping.
3. Compile-time constant caching
Tuple literals composed entirely of constants (numbers, strings, other constant tuples) are built once at compile time and reused. Every call to a function whose body contains return (1, 2, 3) returns the same tuple object. List literals can't be cached because the next line might mutate them, so they're built fresh each time.
def f():
    return (1, 2, 3)

print(f() is f())   # True   ← same object, cached

def g():
    return [1, 2, 3]

print(g() is g())   # False  ← fresh list each call
The combination explains why tuples win on the benchmarks. The differences are well-documented in the CPython source (CPython tuple object docs); reading the C source is illuminating if you want to understand what Python is doing under the hood.
The Tuple-of-Mutables Trap
The most surprising tuple bug. The container is immutable, but its contents may not be. A tuple holding a list still lets you mutate that list.
t = ([1, 2], [3, 4])

t[0] = 99           # TypeError: tuple is immutable
t[0].append(99)     # OK! The list inside the tuple is mutated
print(t)            # ([1, 2, 99], [3, 4])
The tuple "object" hasn't changed (it still references the same two list objects); the list inside it has. This trap explains why a tuple containing a list is unhashable:
The hash function refuses to commit to a value that could change without the tuple noticing. The same trap shows up in shallow-copy semantics (see our shallow vs deep copy explainer): copying a tuple-of-lists with copy.copy creates the SAME inner lists, shared by both copies. For true independence, reach for copy.deepcopy.
Rule: "the tuple is immutable" means "you can't reassign which objects the tuple points at". It does NOT mean "the objects the tuple points at can't change". For truly immutable records of mutable data, build with immutables (use tuples of tuples, not tuples of lists), or use dataclass(frozen=True).
Packing and Unpacking
Tuples shine in multiple assignment, function return values, and parallel iteration.
# Pack
point = 3, 4
rgb = 255, 128, 0

# Unpack
x, y = point
r, g, b = rgb

# Swap (no temporary variable)
a, b = b, a

# Functions returning multiple values
def divmod(a, b):
    return a // b, a % b

quotient, remainder = divmod(17, 5)
The asterisk operator captures the rest:
head, *rest = [1, 2, 3, 4, 5]
# head = 1, rest = [2, 3, 4, 5]

*init, last = [1, 2, 3, 4, 5]
# init = [1, 2, 3, 4], last = 5

first, *middle, last = [1, 2, 3, 4, 5]
# first = 1, middle = [2, 3, 4], last = 5
Unpacking is technically iteration; it works on both tuples and lists. But the syntax was designed for tuples (multiple return values, parallel assignment) and reads most naturally there.
Modern Record Types: namedtuple, NamedTuple, dataclass(frozen=True)
For records with named fields, three modern alternatives improve on plain tuples.
collections.namedtuple (Python 2.6+)
from collections import namedtuple

Point = namedtuple("Point", ["x", "y"])
p = Point(3, 4)

print(p.x, p.y)     # 3 4    named access
print(p[0])         # 3      still positional too
x, y = p            # still unpacks like a tuple
print(p)            # Point(x=3, y=4)   readable repr
A namedtuple IS a tuple subclass with added field names. Everything tuple does (hashability, immutability, indexing, unpacking), namedtuple does. The factory function syntax is the original (and most permissive).
typing.NamedTuple (Python 3.6+)
from typing import NamedTuple

class Point(NamedTuple):
    x: int
    y: int

p = Point(3, 4)
# Same behavior as collections.namedtuple, plus type hints
Class-syntax version of namedtuple with type annotations. Reads more naturally if you're already using type hints; otherwise functionally identical.
dataclasses.dataclass(frozen=True) (Python 3.7+)
from dataclasses import dataclass

@dataclass(frozen=True)
class Point:
    x: int
    y: int

p = Point(3, 4)
print(p.x, p.y)    # 3 4
# p.x = 5  → dataclasses.FrozenInstanceError
hash(p)            # works because frozen=True
A frozen dataclass is NOT a tuple subclass. It's a regular immutable class with named fields. You lose tuple-style positional access (p[0]) and unpacking, but you gain: easier inheritance, custom methods alongside the fields, default values per field, and automatic __init__/__repr__/__eq__ generation. For new code, dataclass(frozen=True) is usually the right choice.
Comparison
Feature
tuple
namedtuple
NamedTuple
dataclass(frozen=True)
Named access
no
yes
yes
yes
Positional access obj[0]
yes
yes
yes
no
Tuple unpacking
yes
yes
yes
no
Type annotations
no
no
yes
yes
Default values
no
partial
yes
yes
Methods on the class
no
limited
yes
yes
Immutable
yes
yes
yes
yes (frozen)
Hashable
if contents are
if contents are
if contents are
if frozen and contents are
For pure positional records, use plain tuples. For named-field records that need tuple compatibility (existing APIs that expect tuples, parallel assignment), use NamedTuple. For new code with no tuple-compatibility requirement, use dataclass(frozen=True).
Use Cases: When Each Wins
Reach for a tuple when:
The collection is a fixed record (coordinates, colors, version numbers like (3, 12, 1)).
You need it as a dict key or set element.
You want a function to return multiple values.
You want the type system to enforce "this won't change".
You're storing millions of small sequences and memory matters.
Reach for a list when:
The length will change over time (items added, removed, filtered).
The items are interchangeable members of the same kind (a list of users, a queue of jobs).
You need in-place sort or other mutation methods.
You'll pass it to APIs that expect a list (some libraries do not accept tuples).
The semantic test: if changing one item changes the meaning of the whole collection, it's a tuple-shaped record. If the items are independent slots that don't carry positional meaning, it's a list.
Common Mistakes
Five traps to watch for:
Mistake 1: (2) is not a one-element tuple. It's the integer 2. Add a trailing comma: (2,).
Mistake 2: assuming an "immutable" tuple is fully immutable. The container is locked; the contents may not be. Tuples of lists are mutable through their elements.
Mistake 3: trying to use a list as a dict key.TypeError: unhashable type: 'list'. Convert to tuple if the contents are hashable, or rethink the data shape.
Mistake 4: choosing a list because "tuples are weird". For fixed records, plain tuples or NamedTuple communicate intent better than lists. Future readers will thank you.
Mistake 5: reaching for namedtuple on new code. The factory-function syntax was 2.6's solution. For new Python 3.6+ code, prefer typing.NamedTuple (class syntax) or dataclass(frozen=True) (more capable). collections.namedtuple remains valid but feels dated in modern codebases.
Frequently Asked Questions
What is the difference between tuple and list in Python?
Lists are mutable; tuples are immutable. Lists are written with square brackets and use methods like append, extend, and remove to change their contents. Tuples are written with parentheses (or just a comma) and have no methods that mutate. The immutability has two consequences: tuples are hashable and usable as dict keys or set elements (lists are not), and CPython can optimize tuples in ways lists don't allow, making them slightly faster and more memory-efficient.
When should I use a tuple instead of a list in Python?
Use a tuple when the collection represents a fixed record (coordinates, RGB color, database row), when you need it as a dict key or set element (requires hashable), when you want to signal to readers that the value should not change, or when performance and memory matter on millions of small fixed-size sequences. Use a list when you'll add, remove, or change items, or when the collection's length varies at runtime.
Why are tuples faster than lists in Python?
Three reasons. First, the C-level tuple object is smaller because it never has to track over-allocated capacity for growth. Second, CPython interns tuple constants at compile time, so the same tuple literal can be reused without re-allocation. Third, tuple operations don't pay for the bookkeeping that supports mutation. For one-off operations the difference is microseconds; for millions of small sequences it adds up to real percentages.
Can a tuple contain mutable objects in Python?
Yes, and this is the most common tuple-related bug. The tuple itself can't be reassigned to point at different objects, but if it holds a list, you can still mutate that list. So t = ([1, 2], [3, 4]); t[0].append(99) changes t[0] to [1, 2, 99] even though the tuple is immutable. The tuple is immutable; its CONTENTS are not necessarily. The same trap explains why a tuple containing a list is unhashable and cannot be a dict key.
What is the difference between namedtuple, typing.NamedTuple, and dataclass?
All three create named-field record types. collections.namedtuple is the original (Python 2.6+), uses a factory function, and produces tuple subclasses with full tuple behavior. typing.NamedTuple is the class-syntax version with type annotations (Python 3.6+); behavior is identical to namedtuple. dataclasses.dataclass(frozen=True) is the modern option (Python 3.7+) and is NOT a tuple subclass; it's a regular immutable class with named fields. Use dataclass for new code unless you specifically need tuple-style positional access; use NamedTuple when both tuple unpacking and immutability matter.
The Bottom Line: Mutability Decides Almost Everything
Lists are mutable; tuples are immutable. Tuples are therefore hashable, slightly faster, more memory-efficient, and the right choice for fixed records. Lists are the right choice for variable-length collections of interchangeable items. The tuple-of-mutables trap catches everyone exactly once; remember that "immutable" applies to the container, not its contents. For records with named fields, dataclass(frozen=True) is the modern default unless you specifically need tuple-style positional access, in which case typing.NamedTuple is the closest match. Plain tuples remain perfect for two-or-three-element positional records and for any function that returns multiple values. For the rest of the most-asked Python concept questions, browse the full Python Concepts Explained index.
Drill Sequence Types Until They're Reflex
CodeGym's Python track turns the tuple-vs-list distinction into muscle memory through 800+ hands-on tasks across 62 levels. The AI validator checks every submission in seconds; the AI mentor explains what broke when you get stuck. First level free; full plan on the pricing page.
Learn Python with hands-on practice →


GO TO FULL VERSION